VL-JEPA: What Changes When a Model Predicts Answer Embeddings?
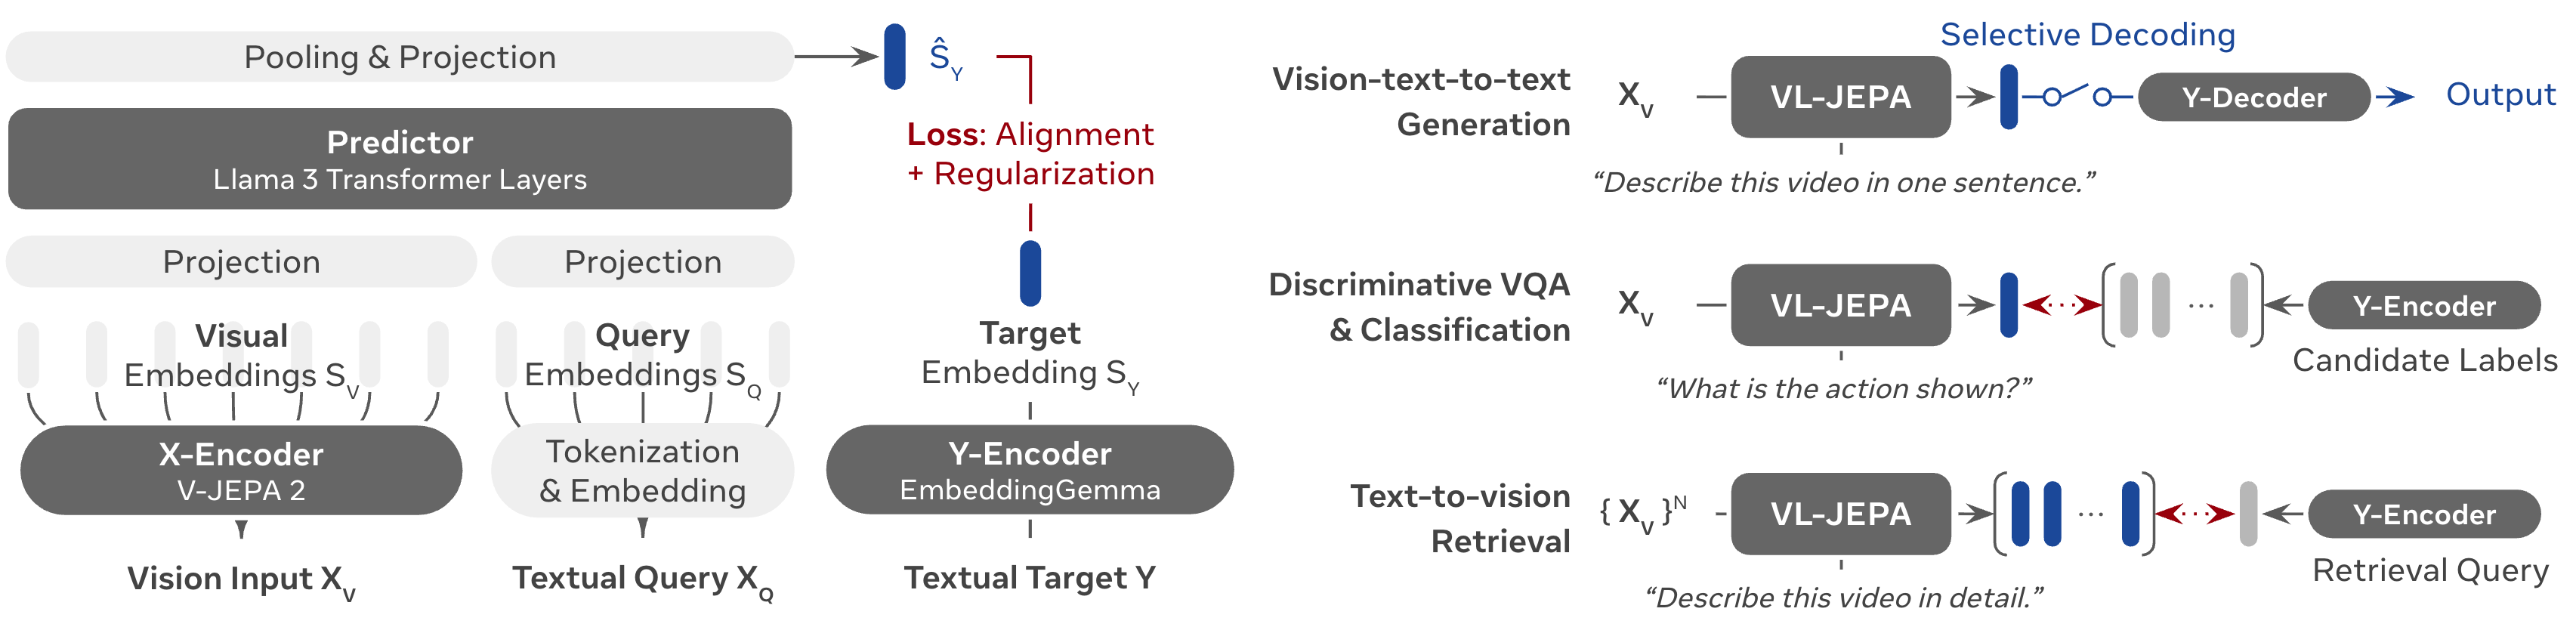
VL-JEPA changes the prediction target and separates visual inference from text decoding. Here is how its objective differs from token prediction and latent diffusion, and what its efficiency results establish.