AI Safety via Debate: How Adversarial Argumentation Solves RL's Hardest Problem
Reinforcement learning works when you can check the answer. A chess engine wins or loses. A code-generation model passes or fails the test suite.
8 articles tagged with #reinforcement learning.
Reinforcement learning works when you can check the answer. A chess engine wins or loses. A code-generation model passes or fails the test suite.
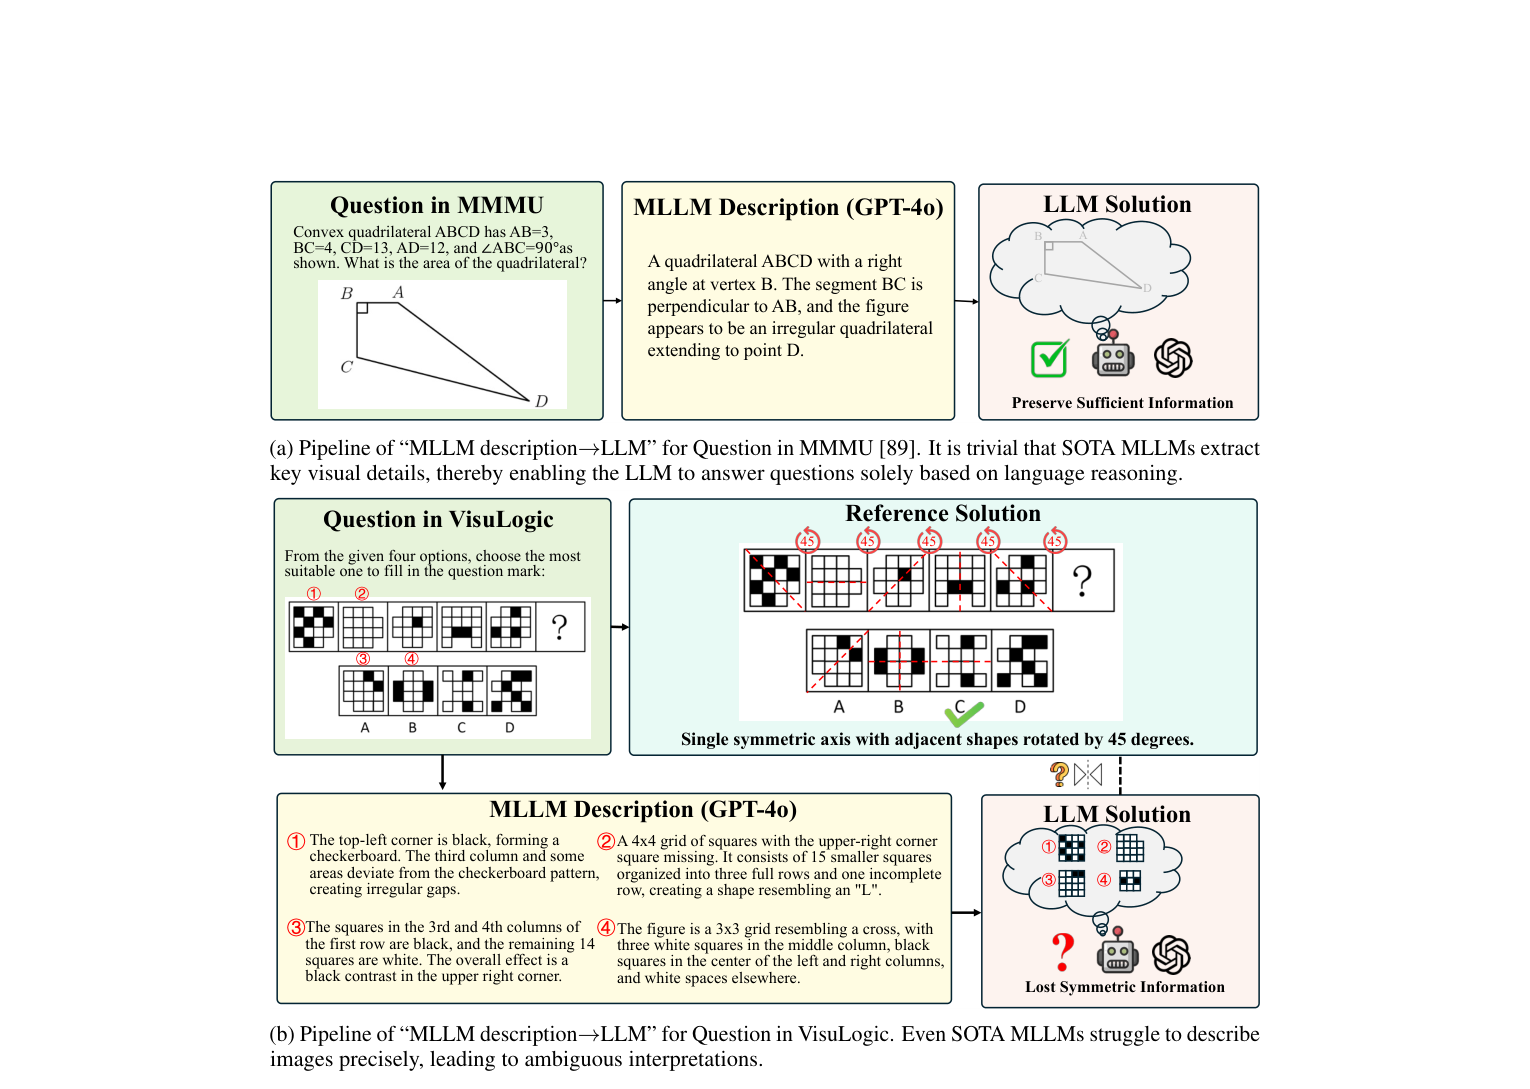
Vision-language models can describe a scene in paragraph-length detail and still fail to tell you whether a red cube is in front of or behind a blue cylinder.
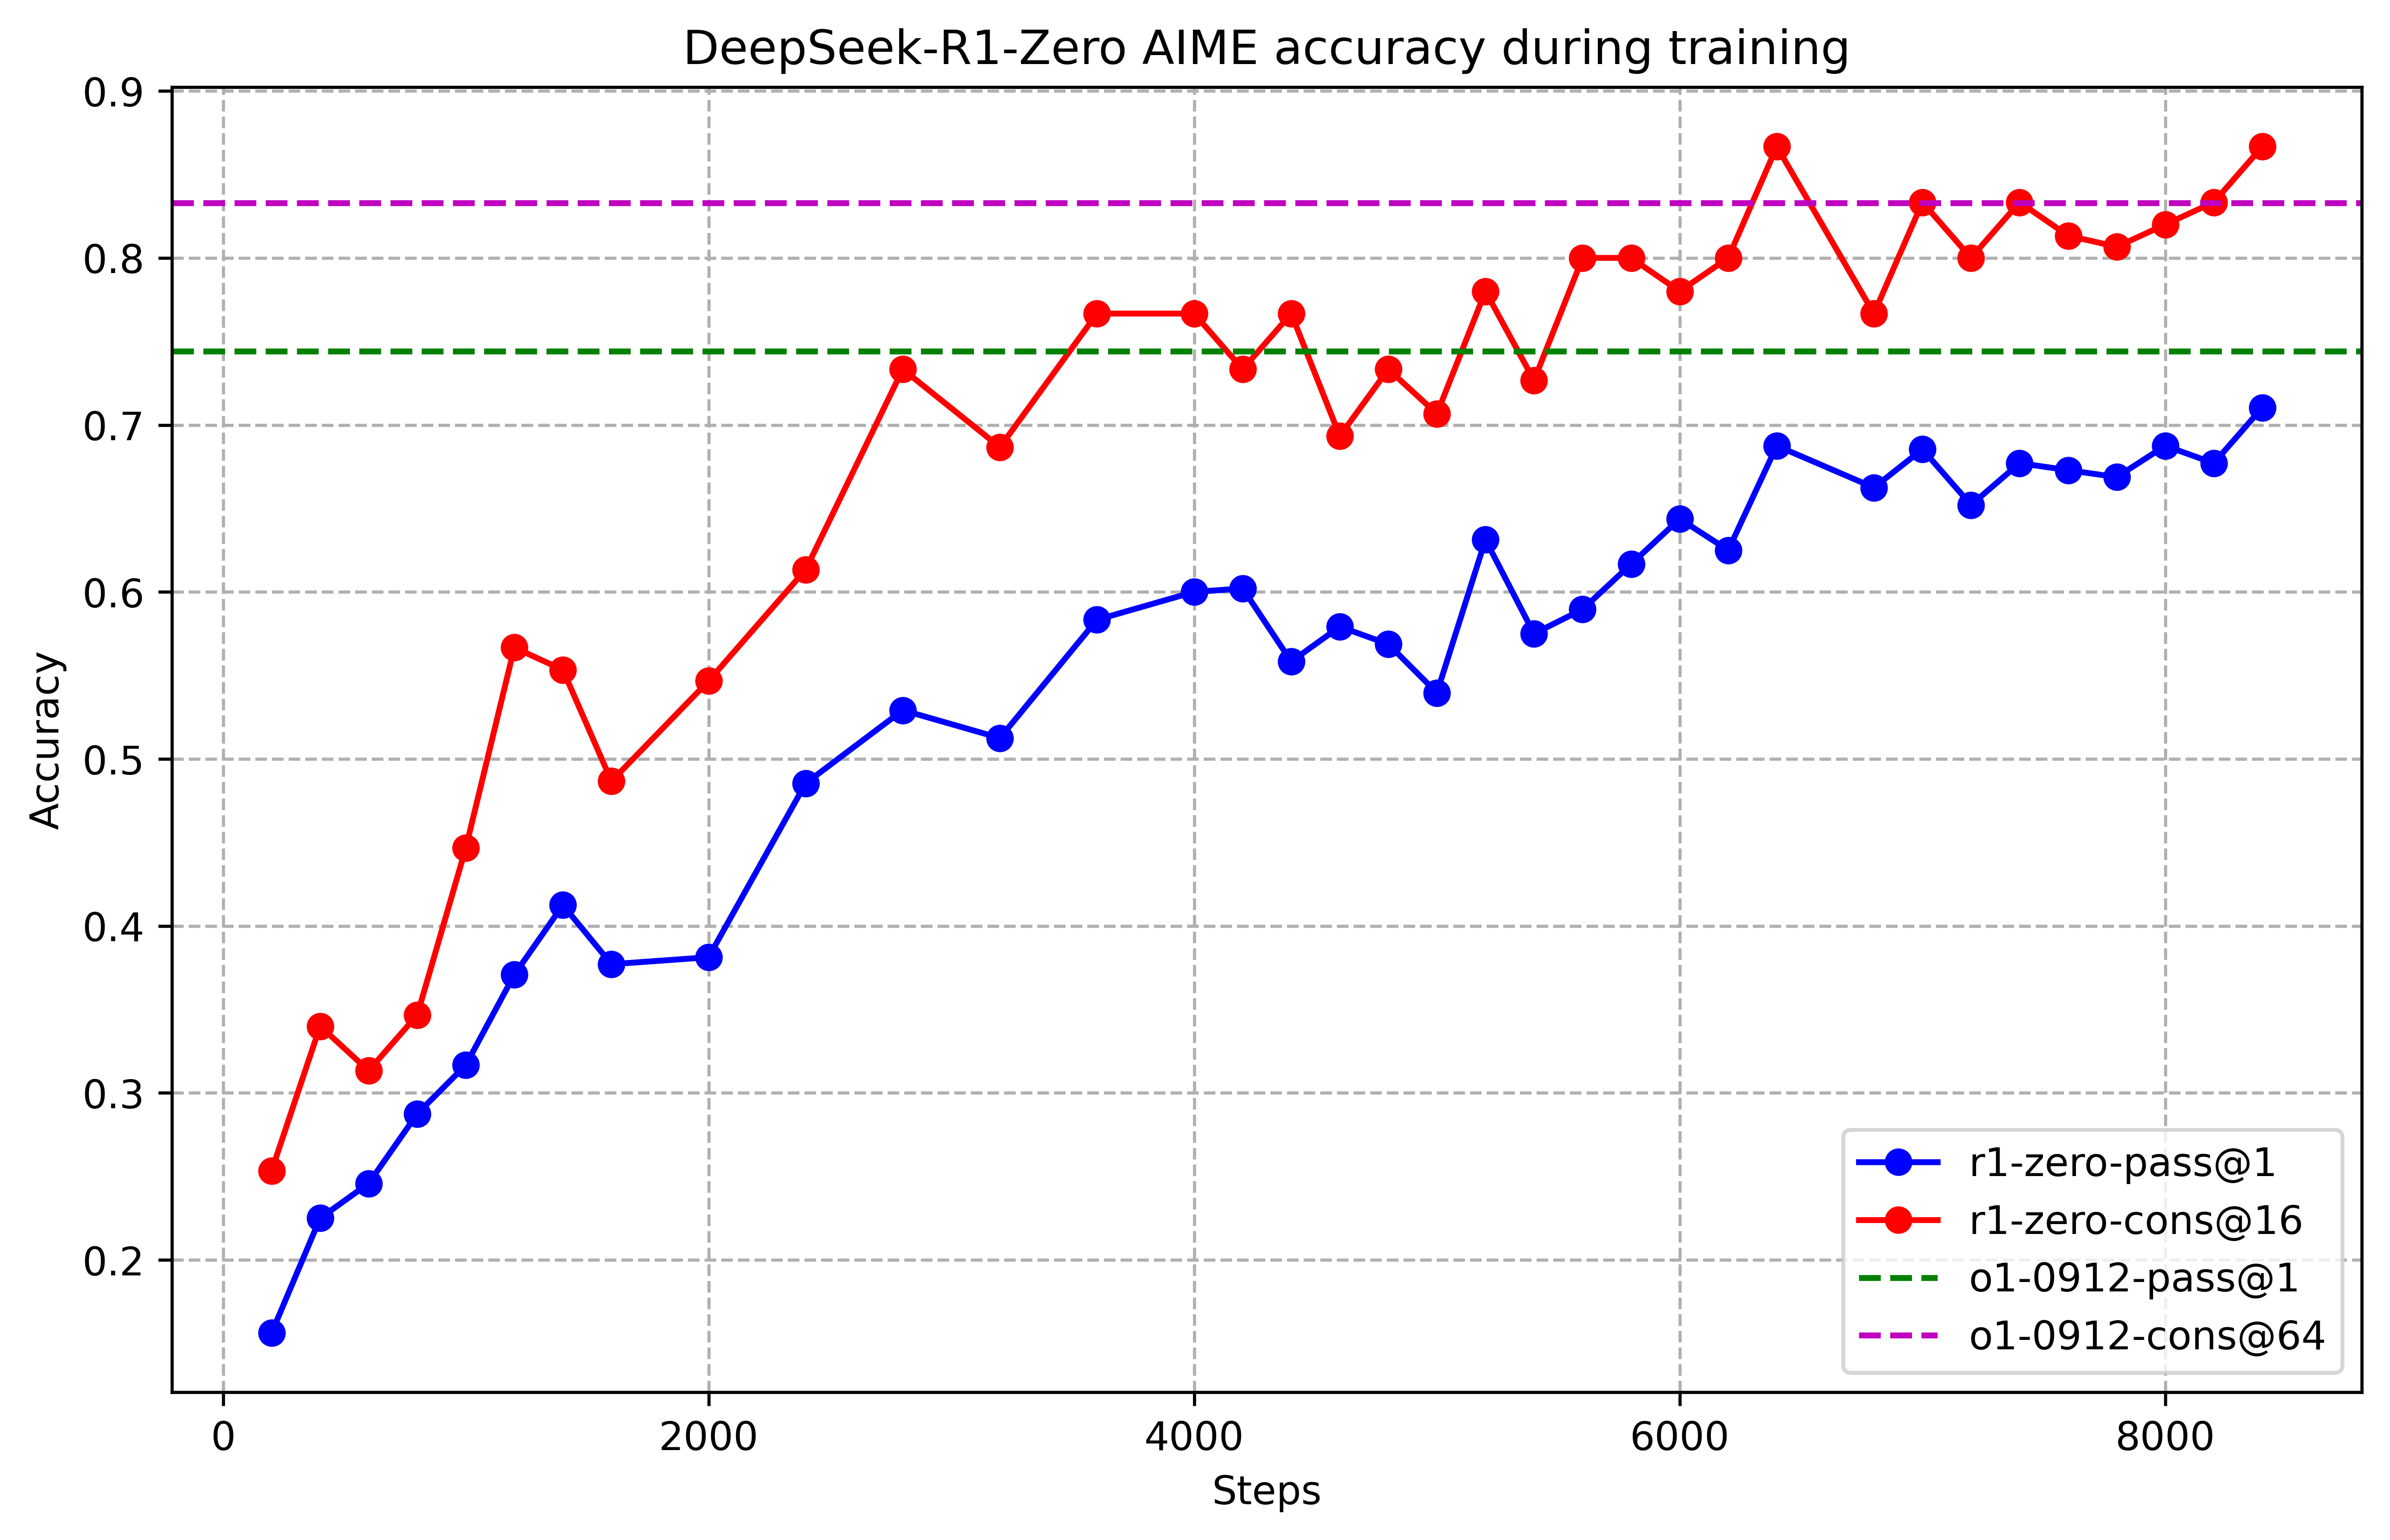
Recent research suggests RL training optimizes search efficiency over existing capabilities rather than expanding reasoning capacity. Here's what the pass@k evidence actually shows.
Understanding when you're working with an environment versus a benchmark changes how you design experiments, interpret results, and communicate findings. This guide covers the practical differences every RL practitioner should know.
Recent research shows 1024-layer networks achieve 2x to 50x improvements in goal-conditioned RL. Here's why extreme depth works now, and when you should consider it for your own agents.
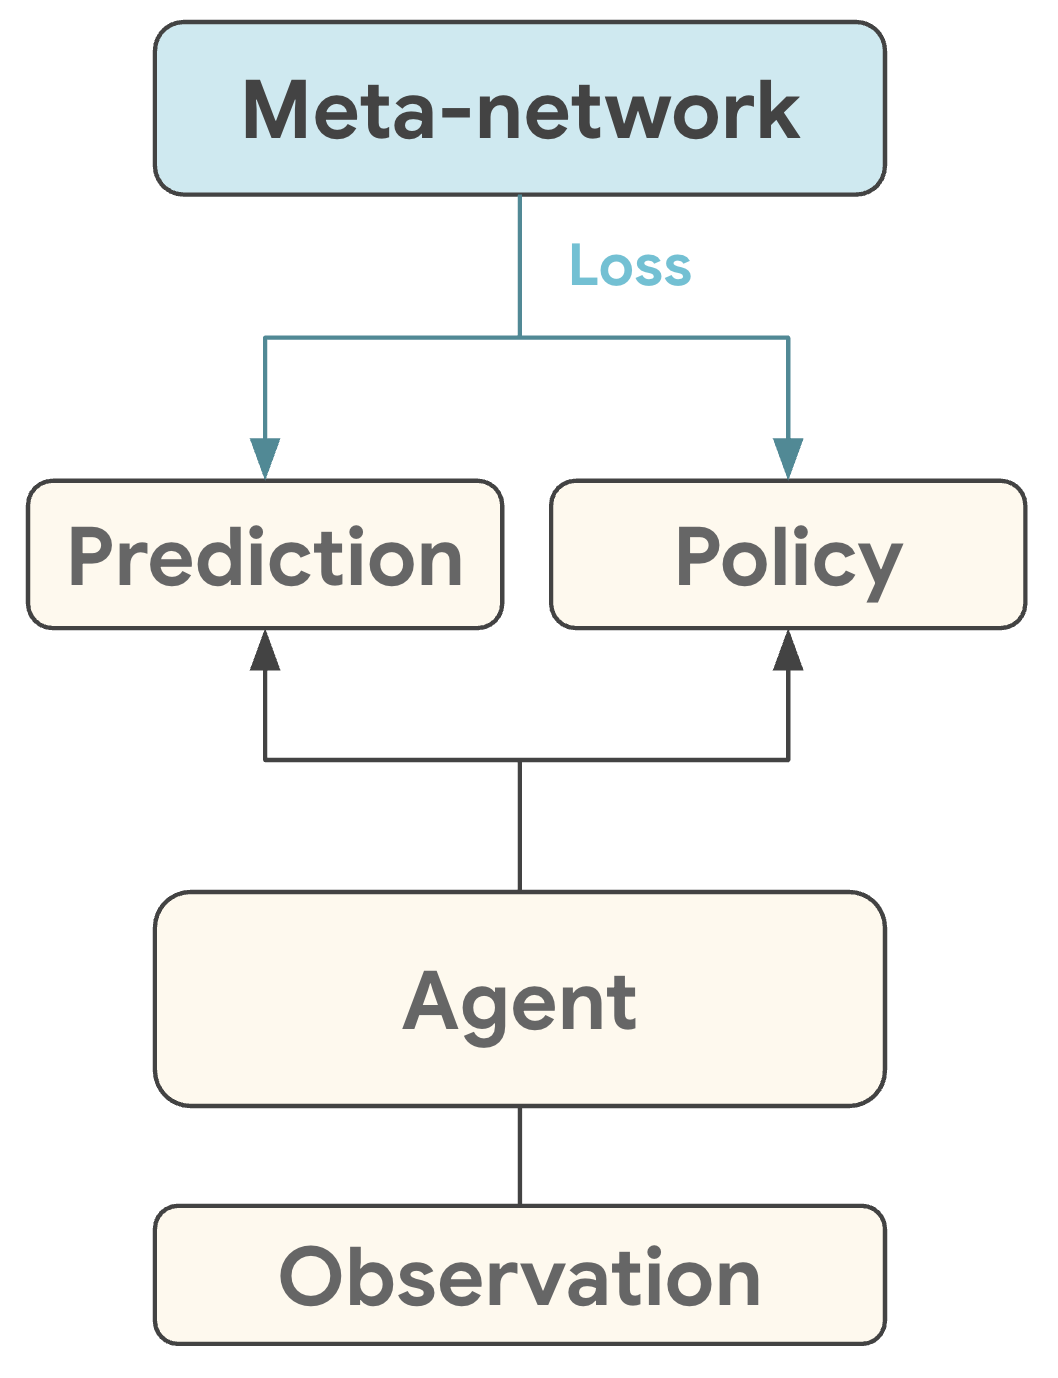
DeepMind's DiscoRL discovers reinforcement learning algorithms that outperform hand-designed methods like PPO and DQN. By treating algorithm design as a meta-learning problem, it found alternatives to value functions and bootstrapping through optimization alone.
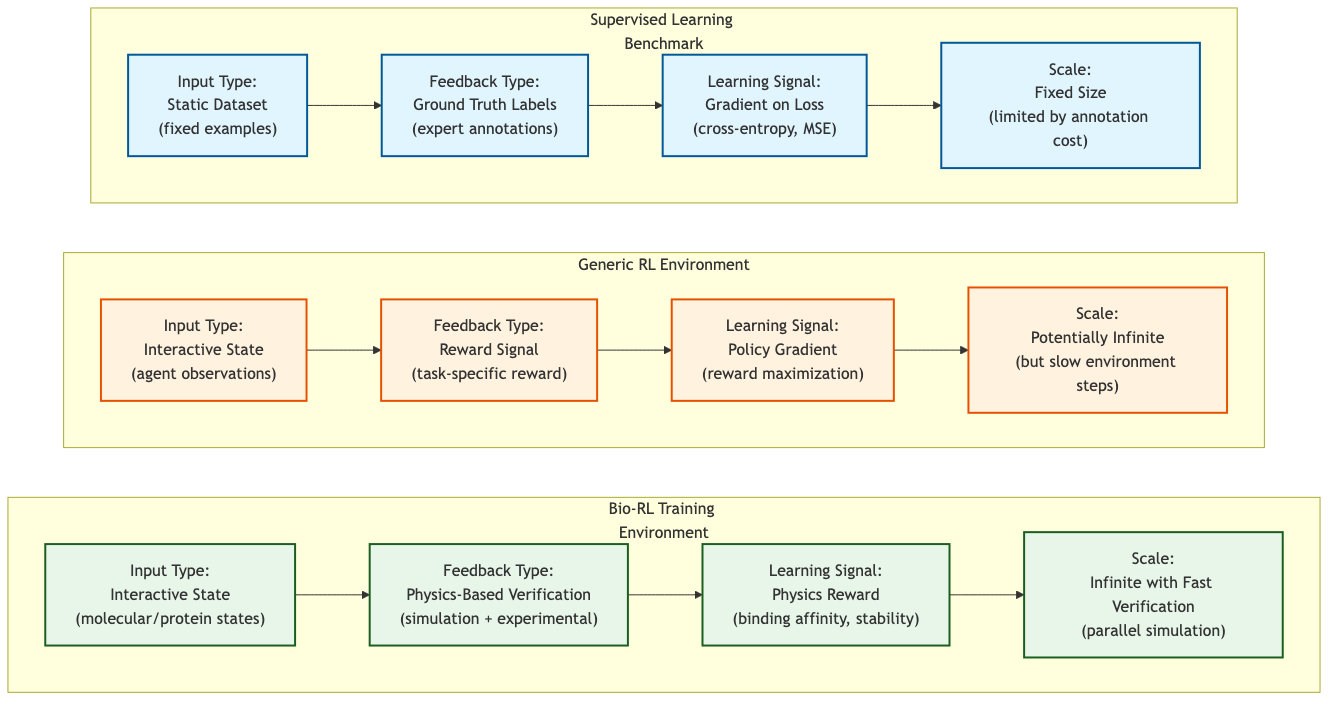
Why biological systems offer the ideal training ground for reinforcement learning: automated verification through physics, not human judgment. From protein design with AlphaFold to RNA folding with ViennaRNA, biology provides the verifiable inverse problems that RL needs at scale.
World models enable AI agents to imagine futures and plan actions, achieving 10-100x better sample efficiency than traditional reinforcement learning. From DreamerV3 collecting diamonds in Minecraft to foundation models like Sora and Genie, world models represent AI's shift from pattern matching to simulating reality itself.